Iterate at the
speed of Lightning.
Build models, run experiments, and fine-tune,
without waiting on GPUs.
Trusted by 450,000+ devs and AI teams


Cloud localhost
See changes instantly without building containers or waiting on jobs.
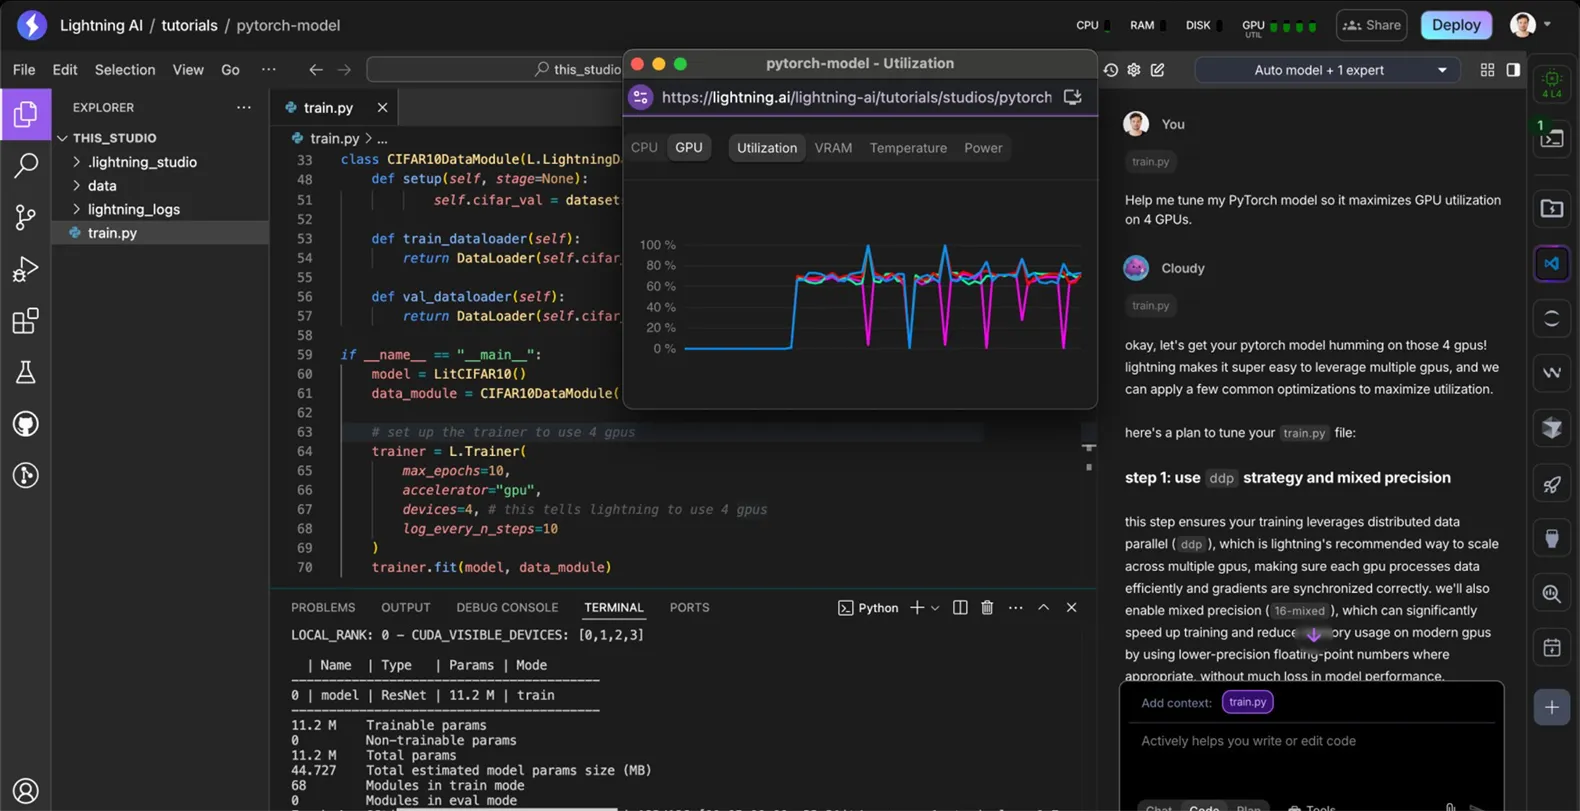
Tune, debug with AI help
Let AI help you find bottlenecks, tune data loading & improve GPU utilization.
The cloud IDE for ML
The collaborative GPU cloud workspace where agents help you build, optimize and ship AI like a pro. Full control for experts. AI help for everyone else.
Get started free
 H100·2,048AVAILABLEA100·3,072AVAILABLEL40S·1,536AVAILABLE
 H200·1,024AVAILABLEL4·4,096AVAILABLE
 H100·896AVAILABLE
 T4·6,144AVAILABLE
 A100·1,280AVAILABLEH200·512AVAILABLEL40S·768AVAILABLEL4·2,304AVAILABLEH100·640AVAILABLE
Never lose work.
Never wait for GPUs.
GPU providers advertise great prices for GPUs you'll never get.
Lightning gives you access to GPUs across 8+ clouds.
- Default (CPU)16 GBFree
- Large (CPU)32 GB$0.51/hr
- X-Large (CPU)64 GB$0.99/hr
- Data prep128 GB$2.22/hr
- Data prep max256 GB$3.60/hr
- Data prep ultra384 GB$4.79/hr
- T416 GB$0.55/hr
- L424 GB$0.79/hr
- L40S48 GB$3.54/hr
- RTXP 600096 GB$4.64/hr
- A10040 GB$2.19/hr
- A10080 GB$1.85/hr
- H10080 GB$5.45/hr
- H200141 GB$4.50/hr
- L424 GB$1.19/hr
- RTXP 600096 GB$4.71/hr
- A10040 GB$2.19/hr
- A10080 GB$2.69/hr
- H10080 GB$5.45/hr
- H200141 GB$4.50/hr
- T416 GB$0.88/hr
- L424 GB$1.20/hr
- L40S48 GB$2.97/hr
- RTXP 600096 GB$4.66/hr
- A10040 GB$2.19/hr
- A10080 GB$2.68/hr
- H10080 GB$5.45/hr
- H200141 GB$4.50/hr
- L424 GB$1.25/hr
- L40S48 GB$4.21/hr
- RTXP 600096 GB$4.63/hr
- A10040 GB$1.55/hr
- A10080 GB$2.67/hr
- H10080 GB$5.82/hr
- H200141 GB$4.50/hr
- B200180 GB$9.86/hr
- 1 TPU32 GB$3.05/hr
- 4 TPU32 GB$3.03/hr
- 8 TPU32 GB$3.03/hr
- 8 TPU95 GB$4.72/hr
Reserve A100, H100, H200, B200 clusters on baremetal, SLURM or Kubernetes.
InquireBilled by the second. Free hours plus up to 30 credits to start.
Trusted by researchers.
Loved by IT.
Full control for researchers - with the guardrails IT demands.
Hardened over 5+ years in the enterprise.
We simply wouldn’t have had the compute access or the ability to iterate so fast. In these past 4-5 months, we’ve been able to do 1.5-2 years worth of work.
The ability to easily scale from development to testing, to extensive market simulations is a game-changer.
Suddenly, scaling compute was effortless, live pipelines could be updated in minutes, and shared studios transformed how we collaborate.
Speed lets us focus on solving real problems, not getting stuck on re-inventing our own wheels.
Instead of spending two weeks just figuring out how to run a script, people are analyzing data on day one.
Setting up a consistent working environment was no longer a challenge. Everyone could see experiments, rerun them, debug issues, and contribute without friction.
This gives us the ability to easily ingest, classify, and structure multimodal data at scale, lowering cost and widening access.
- Auto shutdown idle compute
- Manage compute access by role or team
- Deploy safely with guardrails
- Alerts when things fail
- Enforce budgets by project, team
- Track cloud costs in real-time
- Use AWS/GCP credits
- Bring your own cloud
- Runs on your stack (K8s, etc…)
- Control data access
- SSO + RBAC
- SOC2 & HIPAA